> ## Documentation Index
> Fetch the complete documentation index at: https://dripart-matt-router-pricing-pika-and-guard.mintlify.site/llms.txt
> Use this file to discover all available pages before exploring further.
# ComfyUI OmniGen2 Native Workflow Examples
> Run OmniGen2 natively in ComfyUI for text-to-image generation, instruction-based image editing, and multi-image composition.
OmniGen2 is an open-source unified multimodal generation model from the [VectorSpaceLab](https://github.com/VectorSpaceLab/OmniGen2) research team. A single set of weights handles text-to-image generation, instruction-guided image editing, and subject-driven in-context generation. ComfyUI supports OmniGen2 natively, so all three tasks run locally through the official example workflows.
The model pairs a frozen 3B Qwen2.5-VL vision-language model with a separate 4B diffusion transformer, about 7B parameters in total. The vision-language model reads your reference images and written instructions, and the diffusion transformer turns that understanding into pixels. Because both paths keep their own parameters and image tokenizer, OmniGen2 preserves its visual understanding ability while keeping image quality high.
ComfyUI ships two official workflows for the model: text to image, and image editing from natural language instructions such as "change the dress to blue". The image editing workflow also handles multi-image composition, combining people, reference objects, and scenes from several input images.
Make sure your ComfyUI is updated.
* [Download ComfyUI](https://www.comfy.org/download)
* [Update Guide](/installation/update_comfyui)
Workflows in this guide can be found in the [Workflow Templates](/interface/features/template).
If you can't find them in the template, your ComfyUI may be outdated.
If nodes are missing when loading a workflow, possible reasons:
1. You are not using the latest ComfyUI version (Nightly version)
2. Some nodes failed to import at startup
* [Cloud](https://cloud.comfy.org) will update after ComfyUI stable release.
So, if you find any core node missing in this document, it might be because the new core nodes have not yet been released in the latest stable version. Please wait for the next stable release.
**Model highlights**:
* **Visual understanding**: Reads and analyzes image content through the Qwen2.5-VL foundation model
* **Text-to-image generation**: Creates high-fidelity images from text prompts
* **Instruction-guided image editing**: Applies complex edits from natural language instructions
* **In-context generation**: Combines people, reference objects, and scenes from multiple inputs into new images
**Technical features**:
* **Dual-path architecture**: 3B Qwen2.5-VL text model plus an independent 4B diffusion transformer
* **Omni-RoPE position encoding**: Multi-image spatial positioning and identity distinction
* **Parameter decoupling**: Keeps text autoregressive generation from degrading image quality
* **In-image text**: Generates legible text content inside the generated image
## OmniGen2 Model Download
Since this article involves different workflows, the corresponding model files and installation locations are as follows. The download information for model files is also included in the corresponding workflows:
**Diffusion Models**
* [omnigen2\_fp16.safetensors](https://huggingface.co/Comfy-Org/Omnigen2_ComfyUI_repackaged/blob/main/split_files/diffusion_models/omnigen2_fp16.safetensors)
**VAE**
* [ae.safetensors](https://huggingface.co/Comfy-Org/Lumina_Image_2.0_Repackaged/blob/main/split_files/vae/ae.safetensors)
**Text Encoders**
* [qwen\_2.5\_vl\_fp16.safetensors](https://huggingface.co/Comfy-Org/Omnigen2_ComfyUI_repackaged/blob/main/split_files/text_encoders/qwen_2.5_vl_fp16.safetensors)
File save location:
```
📂 ComfyUI/
├── 📂 models/
│ ├── 📂 diffusion_models/
│ │ └── omnigen2_fp16.safetensors
│ ├── 📂 vae/
│ │ └── ae.safetensors
│ └── 📂 text_encoders/
│ └── qwen_2.5_vl_fp16.safetensors
```
## ComfyUI OmniGen2 Text-to-Image Workflow
OmniGen2: Text to Image
Generate high-quality images from text prompts using OmniGen2's unified 7B multimodal model with dual-path architecture.
 Open and run this workflow directly in Comfy Cloud
Download JSON or search "OmniGen2" in Template Library
**Example output**
### 1. Download Workflow File
### 2. Complete Workflow Step by Step
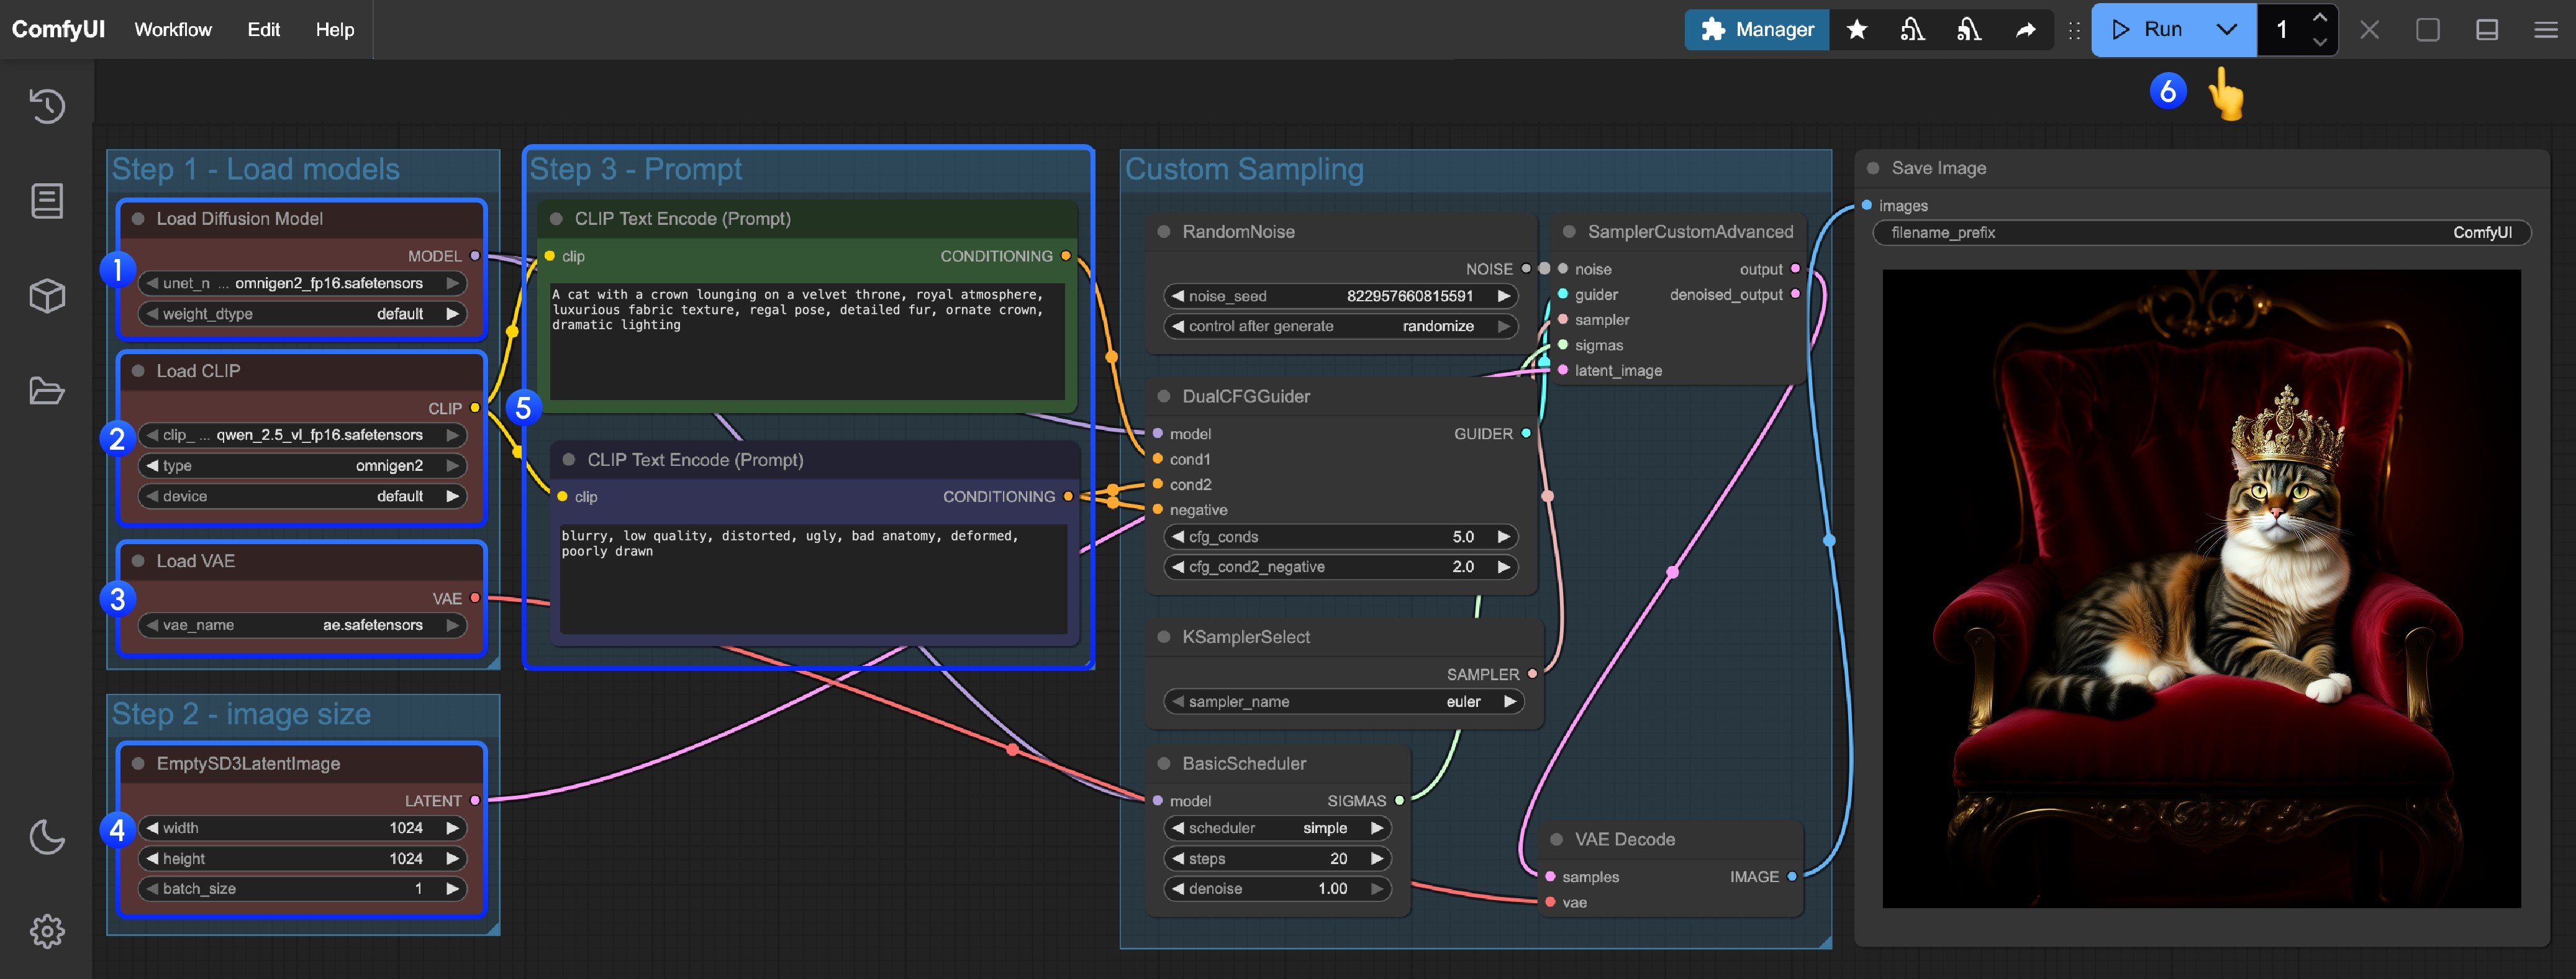 Please follow the numbered steps in the image for step-by-step confirmation to ensure smooth operation of the corresponding workflow:
1. **Load Main Model**: Ensure the `Load Diffusion Model` node loads `omnigen2_fp16.safetensors`
2. **Load Text Encoder**: Ensure the `Load CLIP` node loads `qwen_2.5_vl_fp16.safetensors`
3. **Load VAE**: Ensure the `Load VAE` node loads `ae.safetensors`
4. **Set Image Dimensions**: Set the generated image dimensions in the `EmptySD3LatentImage` node (recommended 1024x1024)
5. **Input Prompts**:
* Input positive prompts in the first `CLipTextEncode` node (content you want to appear in the image)
* Input negative prompts in the second `CLipTextEncode` node (content you don't want to appear in the image)
6. **Start Generation**: Click the `Queue Prompt` button, or use the shortcut `Ctrl(cmd) + Enter` to execute text-to-image generation
7. **View Results**: After generation is complete, the corresponding images will be automatically saved to the `ComfyUI/output/` directory, and you can also preview them in the `SaveImage` node
## ComfyUI OmniGen2 Image Editing Workflow
OmniGen2 has rich image editing capabilities and supports adding text to images.
OmniGen2 Image Edit
Edit images with natural language instructions using OmniGen2's advanced image editing capabilities and text rendering support.
 Open and run this workflow directly in Comfy Cloud
Download JSON or search "OmniGen2 Image Edit" in Template Library
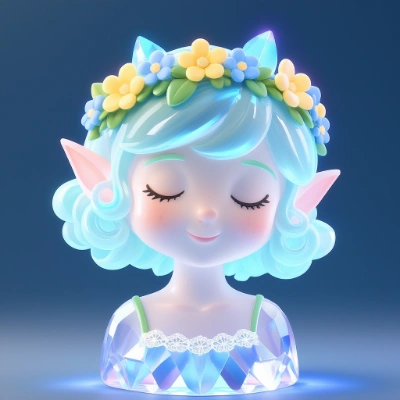
**Input materials**
Upload this file to the matching `LoadImage` node:
`LoadImage` node 16 · `image_omnigen2_image_edit_input_image.png`
**Example output**
### 1. Download Workflow File
### 2. Complete Workflow Step by Step
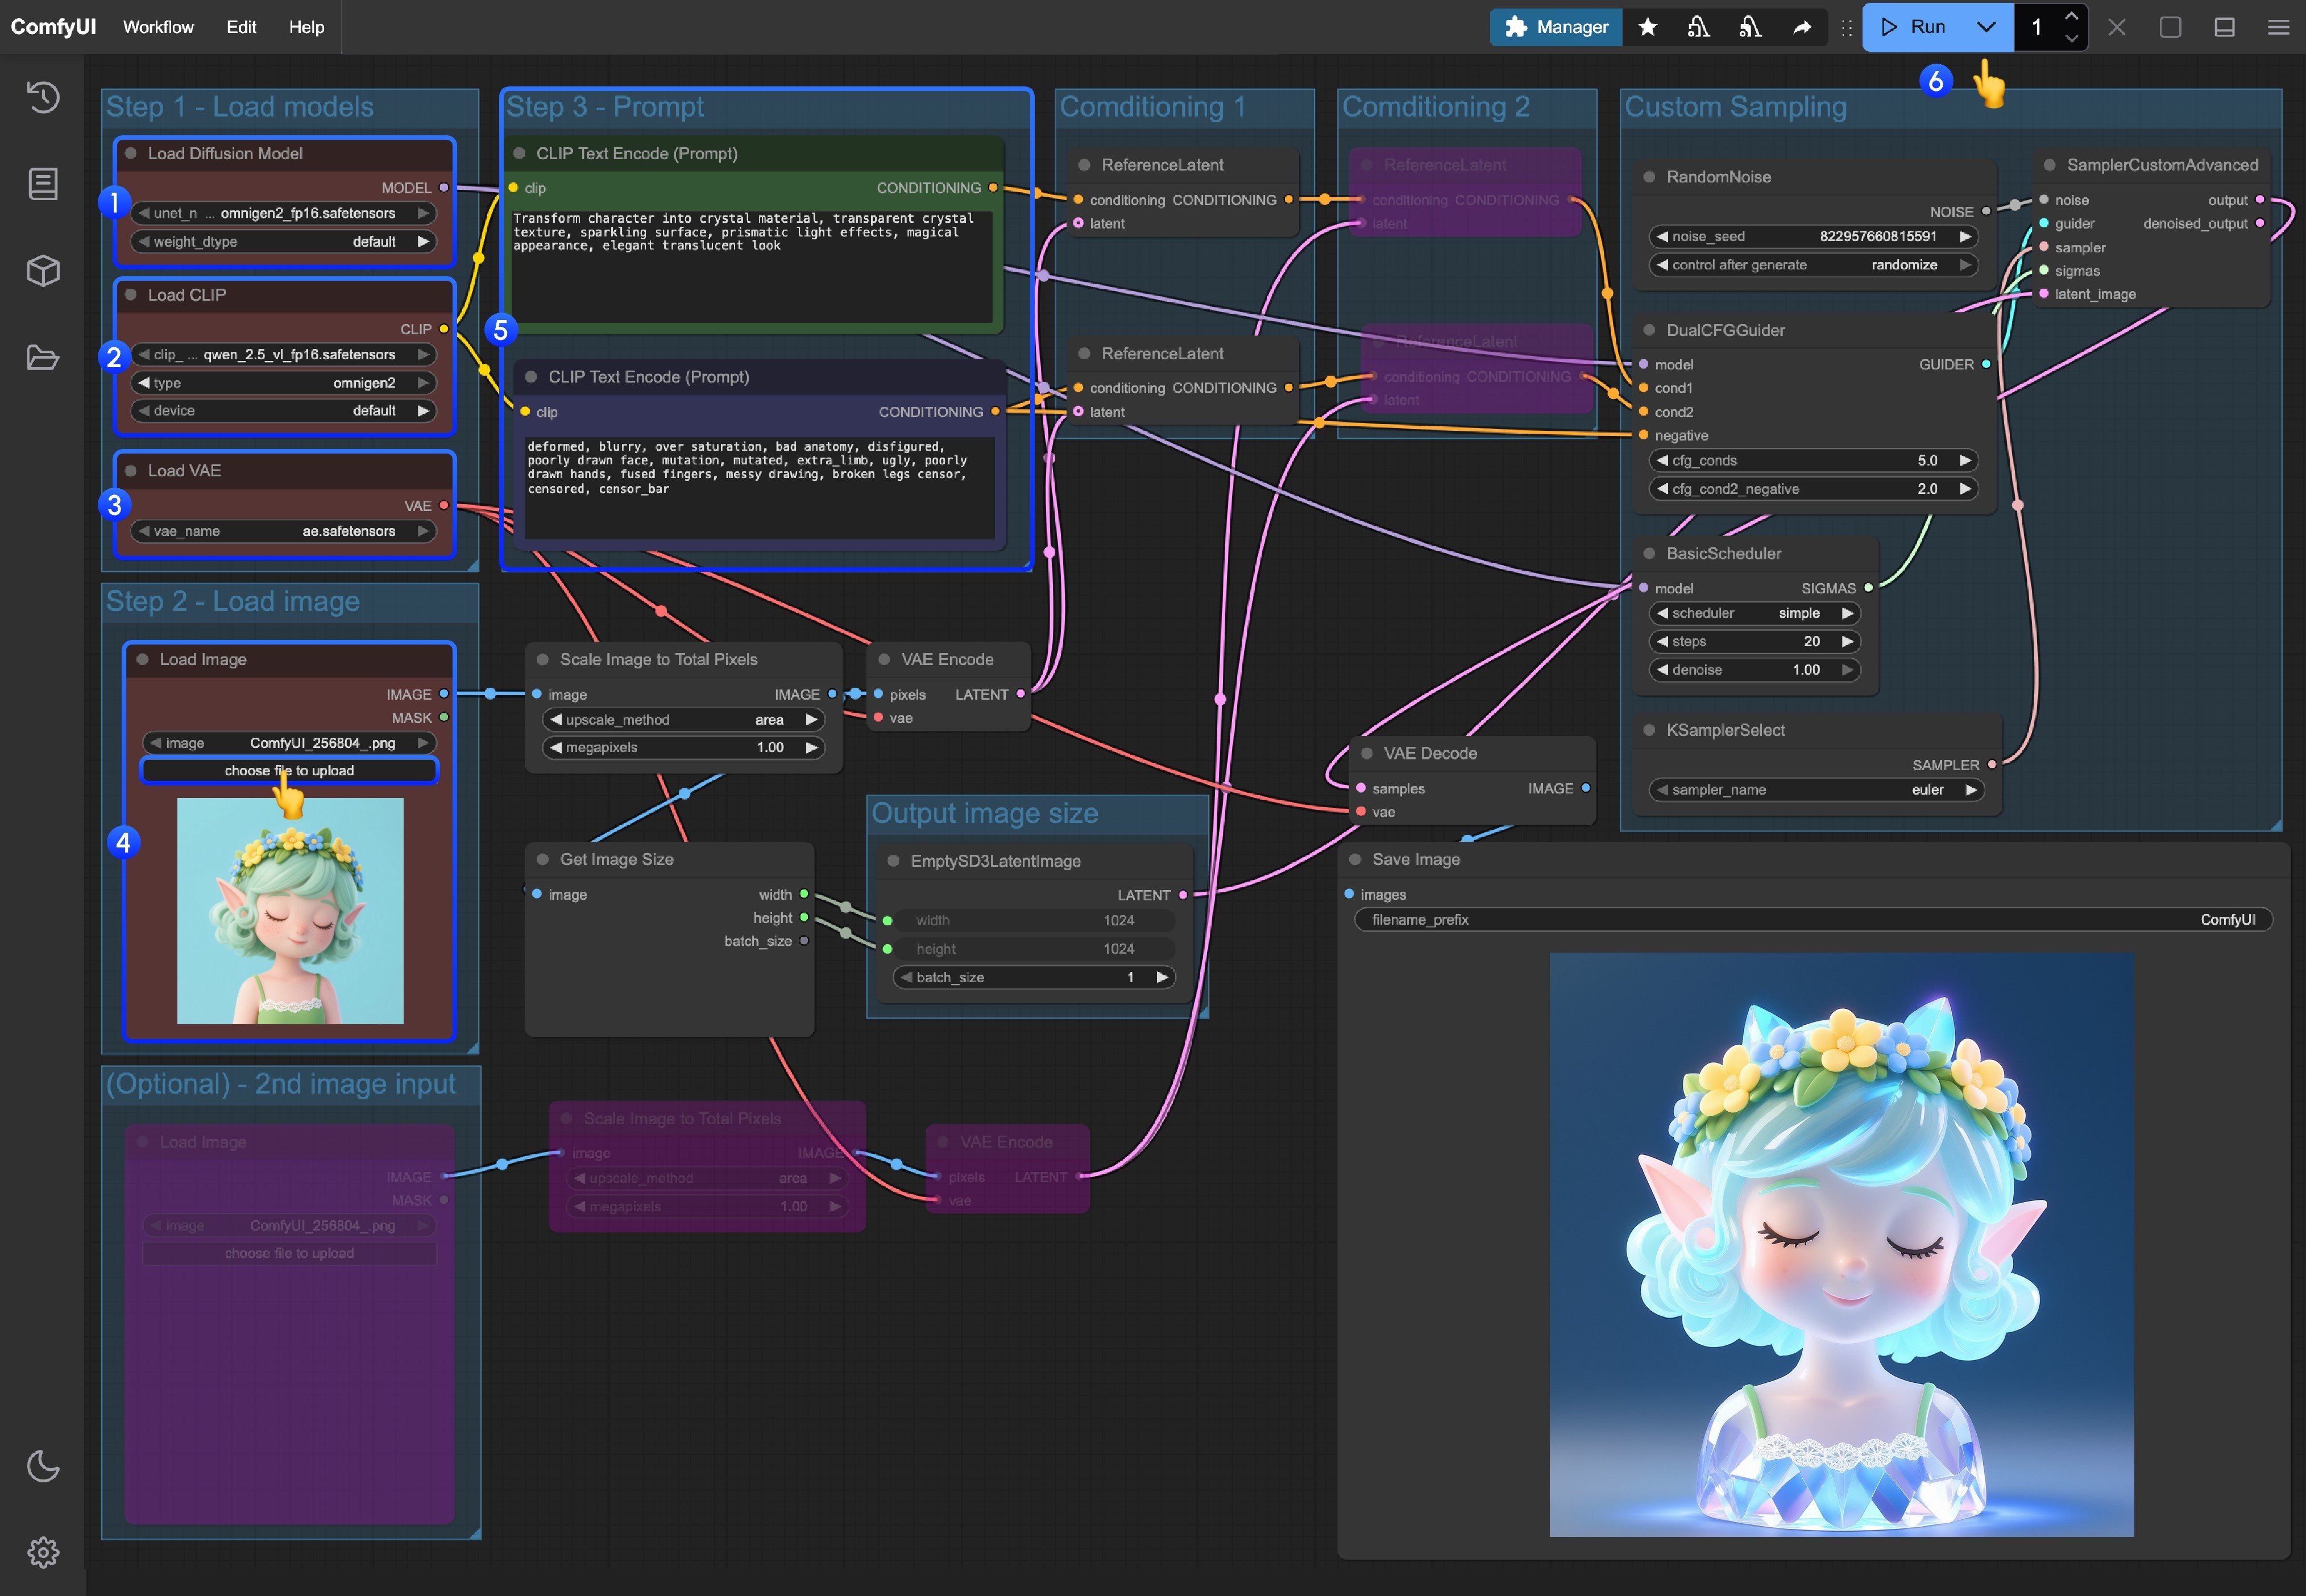 1. **Load Main Model**: Ensure the `Load Diffusion Model` node loads `omnigen2_fp16.safetensors`
2. **Load Text Encoder**: Ensure the `Load CLIP` node loads `qwen_2.5_vl_fp16.safetensors`
3. **Load VAE**: Ensure the `Load VAE` node loads `ae.safetensors`
4. **Upload Image**: Upload the provided image in the `Load Image` node
5. **Input Prompts**:
* Input positive prompts in the first `CLipTextEncode` node (content you want to appear in the image)
* Input negative prompts in the second `CLipTextEncode` node (content you don't want to appear in the image)
6. **Start Generation**: Click the `Queue Prompt` button, or use the shortcut `Ctrl(cmd) + Enter` to execute text-to-image generation
7. **View Results**: After generation is complete, the corresponding images will be automatically saved to the `ComfyUI/output/` directory, and you can also preview them in the `SaveImage` node
### 3. Additional Workflow Instructions
* If you want to enable the second image input, you can use the shortcut **Ctrl + B** to enable the corresponding node inputs for nodes that are in pink/purple state in the workflow
* If you want to customize dimensions, you can delete the `Get image size` node linked to the `EmptySD3LatentImage` node and input custom dimensions
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.